Choosing a model
Which model fits your graphics card.
Embedding models are listed as well. They turn text into vectors for the Library, and they cannot hold a conversation.
Browsing and downloading#
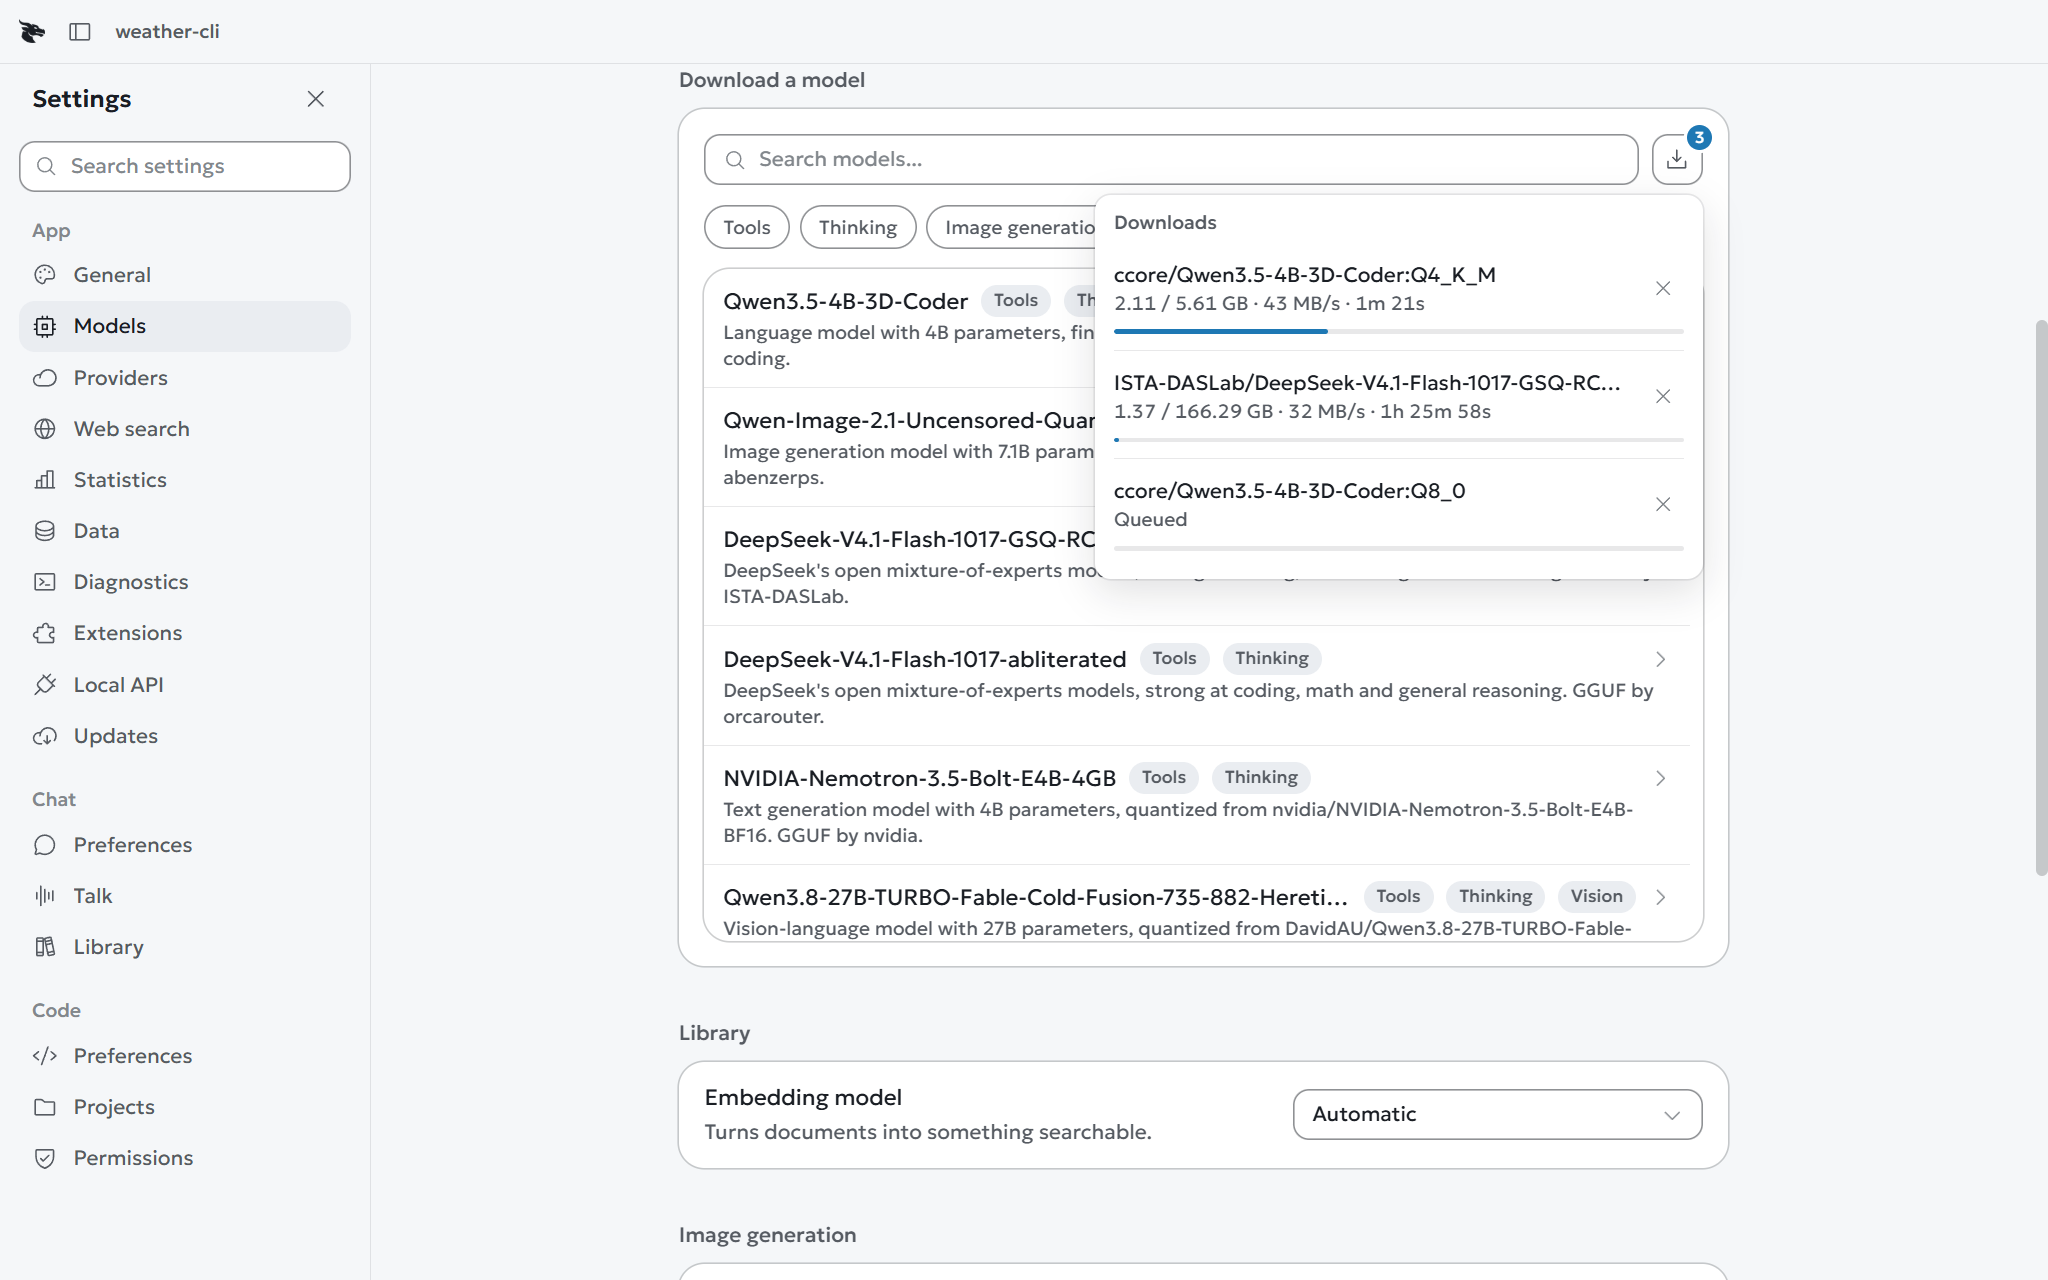
Settings → Models lists the top 100 trending GGUF models on Hugging Face, with search. Click a model to expand its quantization variants. Each shows its file size.
Click a variant's download button. Two downloads run at a time and the rest wait in a queue, so you can line up as many as you like. The download icon at the right of the search bar shows how many are on their way in a red badge. Click it to see each one with its progress, its time remaining and a cancel button. Cancelling a running download removes the partial .download file immediately, and cancelling a queued one just takes it out of the line.
Each installed model carries tags: Chat, Code, Embedding or Images. Embedding and image models are never offered as a chat model. A model the app cannot run yet, such as speech recognition or text to speech, is hidden from the download list.
Loading into memory#
Draggy loads a model only when you send a prompt. While the engine starts, the status line displays the load progress: copying the model into RAM or video memory, reading the model from disk, reading the prompt, and readying the engine.
Windows and Linux#
Draggy picks the best rung that fits. A dense model must fit in video memory, and never more than 80% of system memory, because the engine reads the whole model into RAM first. A machine with under 2 GB of video memory, such as one with integrated graphics, is treated as having half its system memory instead, up to 8 GB.
| Video memory | Dense model |
|---|---|
| From 1 GB | Qwen 3.5 0.8B |
| From 2 GB | Qwen 3.5 2B |
| From 3.5 GB | Qwen 3.5 4B |
| From 6 GB | Gemma 4 E4B |
| From 7.5 GB | Qwen 3.5 9B |
| From 9.5 GB | Gemma 4 12B |
| From 11 GB | Ministral 3 14B |
| From 15.5 GB | Qwen 3.8 27B, Q3 |
| From 20 GB | Qwen 3.8 27B |
| From 23 GB | Qwen 3.8 27B, Q5 |
| From 32 GB | Qwen 3.8 27B, Q8 |
A mixture of experts (MoE) model keeps its active part on the card and the rest in RAM, so it counts video memory and RAM together: 90% of the first plus 80% of the second must hold the file.
| Memory needed | MoE model |
|---|---|
| 14 GB | GPT-OSS 20B |
| 19 GB | Gemma 4 26B |
| 25 GB | Qwen 3.6 35B |
| 40 GB | Qwen 3.6 35B, Q8 |
| 61 GB | Qwen 3.5 122B, Q3 |
| 82 GB | Qwen 3.5 122B |
| 94 GB | Qwen 3.8 Flash-Next, Q3 |
| 116 GB | Qwen 3.8 Flash-Next |
| 135 GB | DeepSeek V4 Flash, Q3 |
| 162 GB | DeepSeek V4 Flash |
| 210 GB | GLM-5.3-Flash |
| 250 GB | GLM-5.3-Flash, Q5 |
The larger ones also ask for a card of 8 GB or more (10 GB from DeepSeek V4 Flash, 12 GB for GLM-5.3-Flash).
Apple silicon#
A Mac has no separate video memory, so Draggy uses 75% of its unified memory and leaves the rest to the system. A base or Pro chip takes the model in the first column. A Max or an Ultra, with far more memory bandwidth, takes the next size up when all of its memory can hold it.
| Unified memory | Base or Pro | Max or Ultra |
|---|---|---|
| From 8 GB | Gemma 4 E4B | Qwen 3.5 9B |
| From 16 GB | Ministral 3 14B | GPT-OSS 20B |
| From 24 GB | Qwen 3.8 27B, Q3 | Qwen 3.8 27B, Q3 |
| From 32 GB | Qwen 3.8 27B, Q5 | Qwen 3.8 27B, Q5 |
| From 48 GB | Qwen 3.8 27B, Q8 | Qwen 3.8 27B, Q8 |
| From 96 GB | Qwen 3.8 27B, Q8 | Qwen 3.8 Flash-Next, Q3 |
| From 128 GB | Qwen 3.8 Flash-Next, Q3 | Qwen 3.8 Flash-Next |
| From 192 GB | DeepSeek V4 Flash, Q3 | DeepSeek V4 Flash |
A Mac with an Intel processor is not Apple silicon. Draggy sizes its models with the rules in the Windows and Linux section above.
Reading the GPU figure#
Settings → Models shows how much of each model fits on the GPU, as a percentage. Green means 98% or more of the model fits. Amber, from 60% to 98%, runs with part of it on the CPU, which is slower. Red, below 60%, is a size too big: step down a size.
A loaded model gets an Unload button there, which frees the video memory without deleting anything.
The talk model#
Voice mode uses its own model, set in Settings → Chat → Talk.